Incident Response
Autoheal's Incident Response agent works alongside your on-call rotation. It investigates a declared incident to an evidence-backed root cause, proposes mitigations for a person to approve, and afterward surfaces changes that would catch the next one sooner.
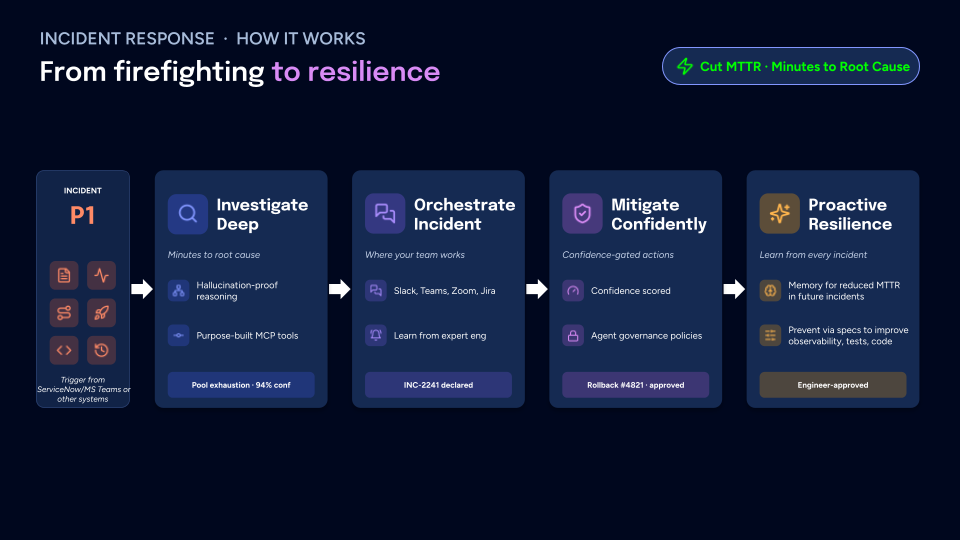
A run starts when an incident is declared in PagerDuty, ServiceNow, Slack, Microsoft Teams or another alert source, or when someone starts one manually.
Investigation
Incident Response defaults to a Deep investigation: the agent generates multiple hypotheses and cross-validates them, then returns a ranked root cause with a confidence score, such as "Pool exhaustion, 94% confidence." Every conclusion is grounded in evidence pulled from your systems and recorded, so you can audit how it reached the answer. The agent gathers that evidence through purpose-built MCP tools that query your observability, code, and infrastructure.
Mitigation
Every proposed mitigation carries an explicit confidence score. A mitigation that writes to one of your systems, such as a rollback, needs an integration with write tools that the agent has access to. A governance policy that gates writes pauses it until a person approves, for example "Rollback #4821, approved."
Proactive Actions
After an investigation closes, Autoheal looks through the agent trace and surfaces proactive actions: concrete, grounded improvements you can make to detect issues sooner and stop them from recurring. Each action is tied back to the investigations that motivated it, so it comes with evidence rather than being a generic best practice.
Proactive actions are organized into four areas:
| Area | What it surfaces |
|---|---|
| Tune alerts | Noisy, missing, or mis-thresholded alerts revealed by how real incidents actually fired |
| Improve observability | Gaps in metrics, logs, or traces that slowed an investigation down |
| Fix code | Code-level changes that would address a recurring root cause |
| Improve testing | Tests that would have caught a regression before it reached production |
How It Integrates
The Incident Response and Alert Triage agents work with your existing on-call workflow:
| Integration Type | Integration Examples | How Autoheal Uses The Integration |
|---|---|---|
| Alerting / On-Call | PagerDuty | Receives alerts and triggers investigations automatically |
| Observability | Datadog, Grafana | Queries metrics, dashboards, and monitors for evidence |
| Error Tracking | Sentry | Pulls error details, stack traces, and exception patterns |
| Source Control | GitHub, GitLab | Reviews recent deployments, commits, and PR history |
| Collaboration | Slack, Microsoft Teams | Invoked via @Autoheal to coordinate the response in-channel |
| ITSM / Incident | ServiceNow | Receives incident triggers and keeps records in sync |
| Logging | Elasticsearch | Searches logs for error patterns and anomalies |
Get Started
- Connect your monitoring tools (Datadog, Grafana, or similar)
- Set up PagerDuty for automatic alert-triggered investigations
- Add skills to your Engineering Context Graph for your most common alert types
- Connect Slack so your team can interact with investigations in real-time